We simplify your work for your agent, so it can do it as well.
Set up Syns for this project: https://syns-setup.pages.dev/SKILL.md
click to copy


| Just a prompt | With a skill | With Syns | |
|---|---|---|---|
| Time with the agent | 38min | 27min | 11min |
| Decisions you had to make | 6 | 4 | 1 |
| Clarity of what it is doing | 1 of 5 | 3 of 5 | 5 of 5 |
| Result you can use | 2 | 1 | 0 |
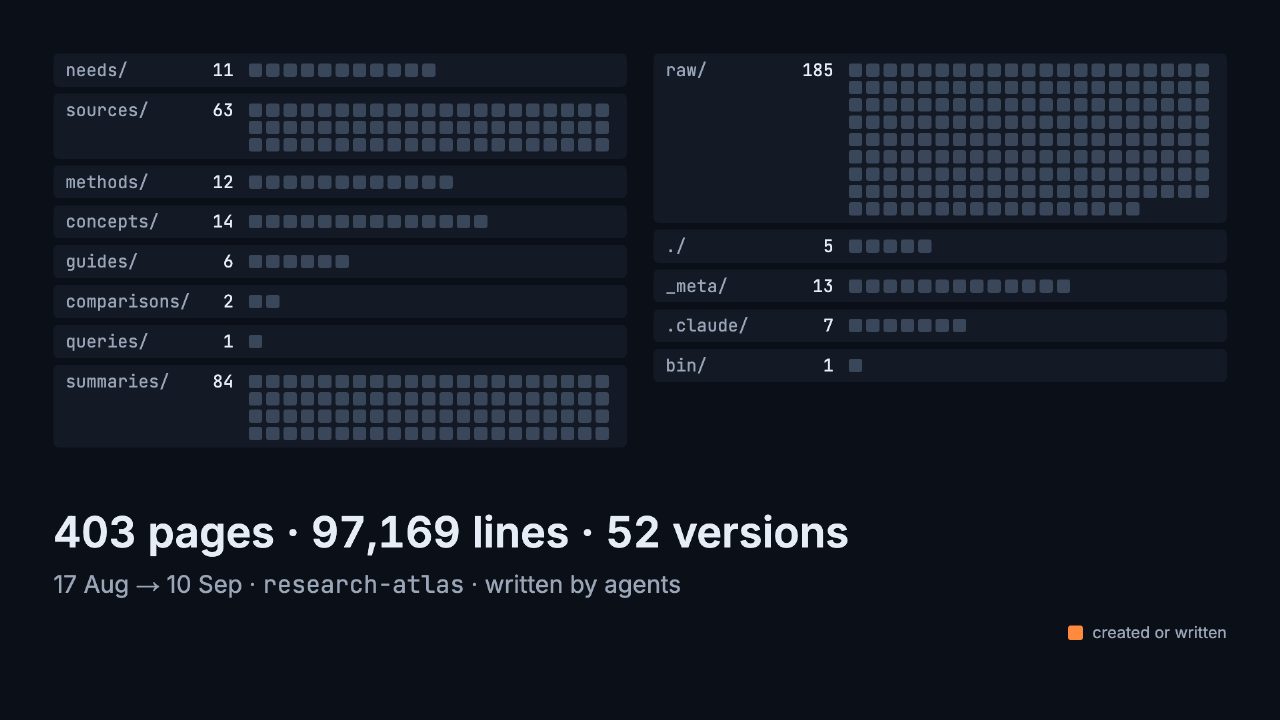
The reasoning that produces the work: plans, specifications, decisions, constraints, instructions, retrospectives. Markdown files, versioned, in a repository of their own. Not your source code, which stays where it is. Not prompts or transcripts, which are how an agent got somewhere rather than what it decided.
Every agent session pulls before its first turn and pushes at the end, so the reasoning is current on every machine and in every sandbox without anyone running a sync step. That is the whole mechanism, and it is why nothing about your workflow changes.
You can, until the work-in-progress problem. An agent writes a document over twenty turns. Commit every turn and you have polluted the code history; commit once and you have lost the progression. There is no good commit granularity for a document a machine is thinking through.
And the reasoning changes at a different rate from the code: a plan is rewritten twenty times while the code it describes changes once. It wants its own history, its own versions, and no ceremony between the agent wrote it and the team can see it.
Related, different object. A memory server holds what an agent decided to remember. Syns holds what someone deliberately wrote down and expects to review, diff, and hand to a person. One is how an agent remembers; the other is how a team keeps something. Teams run both.
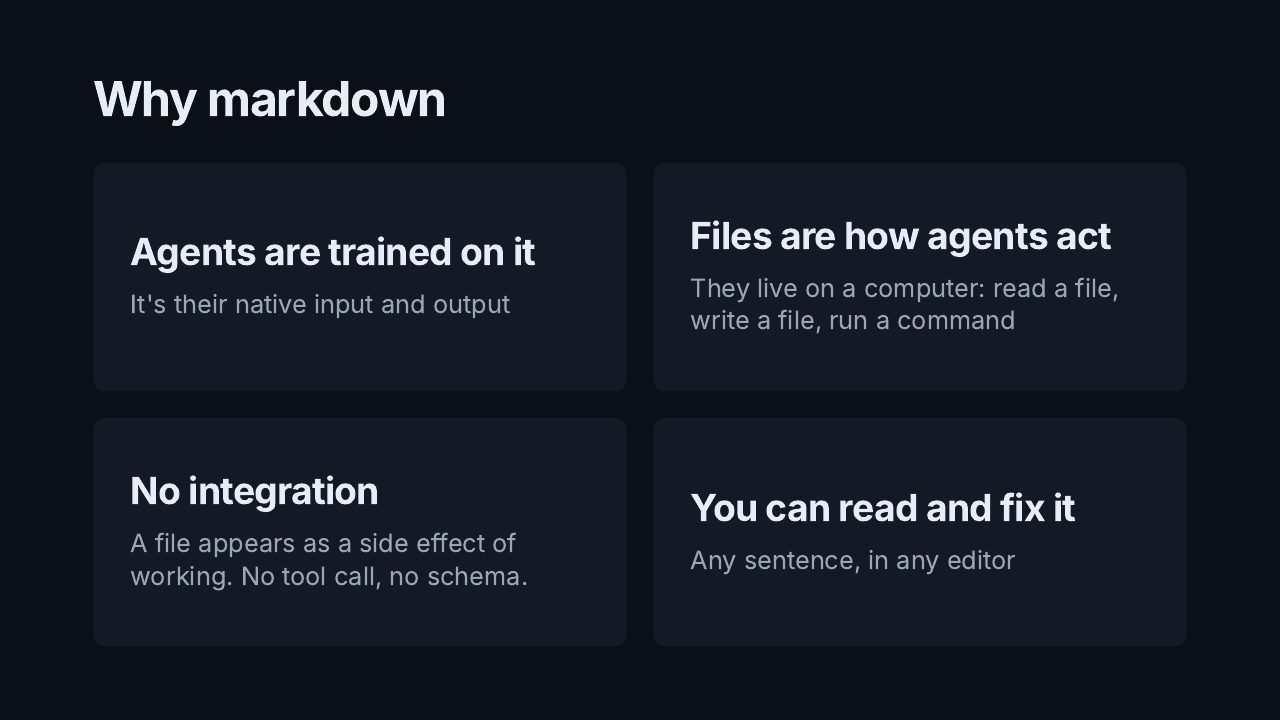
Those work well for humans reading documents. The friction is on the agent side: it needs an integration to reach the content, the round-trip is lossy, and a tool it has to remember to call is a tool it sometimes does not call. A file on disk is always in context because the harness loads it.
These artifacts are read by agents far more often than by people, so the store has to be the thing an agent already knows how to use: files, next to the work, current everywhere.
Syns holds plans and markdown, not source code. It is a separate repository. It cannot see your code and cannot tell whether a private code repository of yours exists. You can also start a repository inside Syns rather than import anything.
They have, each for its own agent. That is the gap: a team running two harnesses side by side is served by neither, and a vendor billing per token has no interest in a layer that reduces reads. The heaviest agent users mix vendors deliberately, and they will not keep their decision layer with one of the parties they want to switch between.
Syns is vendor-neutral and tool-agnostic. It sits underneath the workflow tools, not in front of them, and every new tool that produces reasoning as markdown makes it more useful.
Three places. The prompt gets shorter, because the project's reasoning carries the context you would otherwise re-explain. The questions get fewer and better, because the agent reads what was decided before it decides anything. And the result needs less rework, because the constraints it has to respect are in its context rather than in your head.
The same reasoning is shared by every agent on the team, so the second dispatcher gets the same start as the first.
A skill gives your agent a method. Syns gives it your project: what was decided, what was ruled out, and what the last runs produced. Method is generic. Your reasoning is not, and it is what the agent needs to start informed, ask once, and write back what it decided.
One person, one agent, one machine: your instruction file and a git repository do all of this. Keep them. Syns starts mattering at the second reader, or the second session that needs to know what the first one decided.
Free for personal use, no credit card, no trial clock. Sign in with GitHub, Google or GitLab. Any agent that can fetch a URL can run the setup line.
A page the agent wrote for that step. Any agent that can write a file can write one, and several harnesses render them. It is not a Syns screen: the same run in a terminal reads the same files and reaches the same result; the page is how it keeps you informed and asks its one question.
From the run shown above, one task in both conditions, counted the same way on both sides: minutes with the agent, decisions it asked you to make, moments you could say what it was doing, rework rounds to a result you accepted. They describe that run; the measured comparison across tasks is still to come, and these figures are replaced by it when it does.
Your agent, your editor, your tracker, your code host. Keep the instruction file you already have. Syns installs from one line, runs in the background, and rolls in as slowly as you like. A push that lands after a teammate's is rejected rather than silently overwriting their work; agents read each other's pushed work and adjust.